1 BCI Competition IV Dataset 2a
1 Dataset Overview
| Field | Details |
|---|---|
| Modality | EEG + EOG |
| Paradigm/task | Cued four-class MI left hand/right hand/feet/tongue |
| Participants | 9 healthy |
| Channels | 22 EEG + 3 EOG (25 acquisition channels) |
| Sampling rate | 250 Hz |
| Classes/events | 4 classes |
| Sessions/runs | 2 sessions, 6 runs/session |
| Trials | 288 trials/session = 576/participant (48/run; 12/class/run) |
| Trial/epoch duration | 4 s MOABB imagery epoch (raw cue sequence 6 s) |
| Hardware/montage | BrainAmp MR plus, Ag/AgCl left-mastoid reference, right-mastoid ground custom 22-channel montage |
| License | CC BY-ND 4.0 |
| Data/source | Data Competition |
| MOABB | BNCI2014_001 |
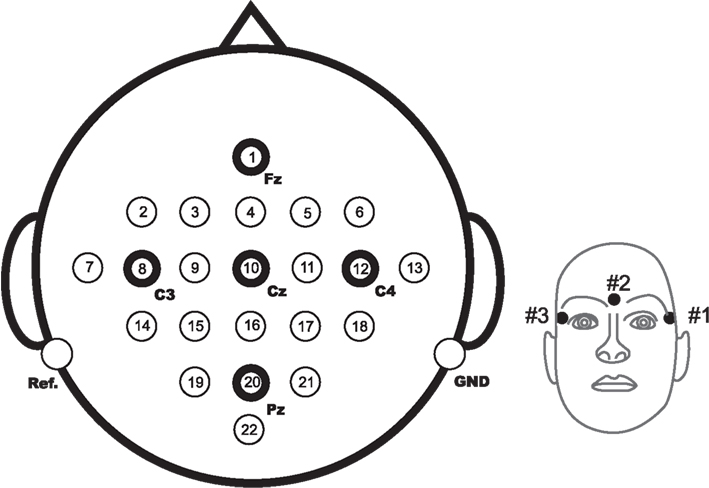
1.1 Montage
Electrodes positions:
2 SPD- and Correlation-Manifold
| Model | Paper | Geometry / Family | Protocol on 2a | Result on 2a | Domain Adaptation | Notes |
|---|---|---|---|---|---|---|
| Tensor-CSPNet | Ju et al. (2022) | SPD-manifold geometric deep learning | Within-session + cross-session | CV(T): 75.98 ± 14.26; CV(E): 74.92 ± 14.63; Holdout (T → E): 72.96 ± 14.98 | No | 4 classes |
| mAtt | Pan et al. (2022) | SPD-manifold attention with BiMap/ReEig | Cross-session | 74.71 ± 5.01 | No | 4 classes; first session train, second session test |
| CorAtt-OLM | Hu et al. (2025) | Correlation-manifold attention | Cross-session | 75.01 ± 2.78 | No | 4 classes; first session train, second session test |
| CorAtt-LSM | Hu et al. (2025) | Correlation-manifold attention | Cross-session | 74.47 ± 2.43 | No | 4 classes; first session train, second session test |
| CorAtt-MIX | Hu et al. (2025) | Correlation-manifold attention | Cross-session | 75.56 ± 1.58 | No | 4 classes; best CorAtt variant on 2a |
| TSMNet (SPDDSMBN) | Kobler et al. (2022) | SPD-manifold network with domain-specific BN | Inter-session | 69.0 ± 3.6 | Yes | Same paper also reports inter-subject: 51.6 ± 16.5 |
| SPD-Net | Peng et al. (2023) | Direct SPDNet baseline | Original train/test split | 76.9 ± 17.1 | No | 2 classes only: left vs right hand; pooled IIIa+2a (12 subjects), not 2a-specific |
| SPD-Mani-Net | Peng et al. (2023) | SPDNet-style Siamese shrinkage network | Original train/test split | 83.1 ± 14.9 | No | 2 classes only: left vs right hand; pooled IIIa+2a (12 subjects), not 2a-specific |
| SPD-Mani-Net+Reg | Peng et al. (2023) | Siamese shrinkage network + inter-subject reg. | Merged multi-subject | 53.28 ± 17.78 | No | 4 classes; pooled IIIa+2a (12 subjects), not 2a-specific |
| SPD-DANN | Cheng et al. (2025) | SPD-manifold adversarial network | Cross-subject | 44.9 | Yes | Cross-subject DA only, not comparable to within-session/cross-session subject-specific setups |
2.1 Protocol-Unclear Benchmark Extracts
The local extract of the Chevallier et al. (2024) pipeline benchmark on BNCI2014-001 does not identify enough protocol detail (within-session, cross-session, or cross-subject), so it is kept here without guessing a protocol.
| Pipeline | BNCI2014-001 |
|---|---|
| ACM+TS+SVM | 77.82±12.23 |
| CSP+LDA | 65.99±15.47 |
| CSP+SVM | 66.88±15.22 |
| DLCSPauto+shLDA | 66.31±15.36 |
| DeepConvNet | 35.29±8.26 |
| EEGITNet | 35.55±6.35 |
| EEGNeX | 45.62±15.29 |
| EEGNet-8,2 | 60.46±20.20 |
| EEGTCNet | 41.65±13.73 |
| FBCSP+SVM | 66.53±12.05 |
| FgMDM | 70.14±15.13 |
| MDM | 61.60±14.20 |
| ShallowConvNet | 72.47±16.50 |
| TS+EL | 72.38±14.85 |
| TS+LR | 71.97±15.46 |
| TS+SVM | 70.76±15.08 |
| Average | 61.34 |
3 Within-Session / Within-Subject
| Model | Validation | Result (%) | Kappa | Source |
|---|---|---|---|---|
| Deep ConvNet | 10-fold CV | 72.20 ± 12.12 | — | Mane et al. (2021) |
| EEGNet-8,2 | 10-fold CV | 73.13 ± 8.52 | — | Mane et al. (2021) |
| FBCNet | 10-fold CV | 79.03 ± 13.17 | — | Mane et al. (2021) |
| FBCSP-SVM | 10-fold CV | 75.89 ± 13.87 | — | Mane et al. (2021) |
3.1 Mane et al. (2021)
Table S3. Classification accuracies for each subject in BCIC-IV-2A Dataset. (10-fold cross-validation part.)
| Subject No. | 10-fold cross validation — FBCSP-SVM | 10-fold cross validation — Deep Convnet | 10-fold cross validation — EEGNet-8,2 | 10-fold cross validation — FBCNet |
|---|---|---|---|---|
| 1 | 85.31 | 71.03 | 72.86 | 85.76 |
| 2 | 64.51 | 52.05 | 56.25 | 61.07 |
| 3 | 90.00 | 82.41 | 83.39 | 94.51 |
| 4 | 64.02 | 58.93 | 67.54 | 68.84 |
| 5 | 73.66 | 73.57 | 76.38 | 82.54 |
| 6 | 52.72 | 62.50 | 67.05 | 58.71 |
| 7 | 92.10 | 79.33 | 73.53 | 93.08 |
| 8 | 88.62 | 82.41 | 80.27 | 86.21 |
| 9 | 72.10 | 87.59 | 80.94 | 80.54 |
| Avg | 75.89 | 72.20 | 73.13 | 79.03 |
| Std | 13.87 | 12.12 | 8.52 | 13.17 |
3.1.1 Ju et al. (2022)
Table II. Average accuracies and standard deviations for the subject-specific analysis of MI-KU (54 subjects) and BCIC-IV-2a (9 subjects). Each result is average accuracy (standard deviation); the best-performing number for each analysis is bold. (within-session part.)
| Method | MI-KU — CV (S1) % | MI-KU — CV (S2) % | BCIC-IV-2a — CV (T) % | BCIC-IV-2a — CV (E) % |
|---|---|---|---|---|
| FBCSP | 64.41 (16.28) | 66.47 (16.53) | 73.57 (15.13) | 72.46 (16.02) |
| MDM | 50.47 (8.63) | 51.93 (9.79) | 62.96 (14.01) | 59.49 (16.63) |
| TSM | 54.59 (8.94) | 54.97 (9.93) | 68.71 (14.32) | 63.32 (12.68) |
| SPDNet | 57.88 (8.68) | 58.88 (8.68) | 65.91 (10.31) | 61.16 (10.50) |
| EEGNet | 63.35 (13.20) | 64.86 (13.05) | 69.26 (11.59) | 66.93 (11.31) |
| ConvNet | 64.21 (12.61) | 62.84 (11.74) | 70.42 (10.43) | 65.89 (12.13) |
| FBCNet | 74.16 (12.60) | 73.81 (13.99) | 77.26 (14.82) | 76.58 (13.09) |
| Tensor-CSPNet | 74.95 (15.27) | 75.92 (14.63) | 75.98 (14.26) | 74.92 (14.63) |
3.2 Ouahidi et al. (2024)
Table II. Performance comparison to literature methods on BNCI using offline evaluation setups. Standard deviations (stds or ±) represent variation across subjects. (within-subject part.)
EEG-SimpleConv through TIDNet are deep-learning methods; CSP+LDA, FBCSP+LDA, and TS+LDA are machine-learning methods.
| Method | Within-Subject (W-S) |
|---|---|
| EEG-SimpleConv | 78.4 ± 10.6 |
| EEG Conformer [30] | 78.7 ± 14.4 |
| EEG-ITNet [22] | 76.7 ± 11.1 |
| EEG-TCNet [18]¹ | 74.5 ± 10.1 |
| CNN-SPDNet [35] | 74.2 |
| Shallow ConvNet [12] | 73.7 |
| EEGNet [15]¹ | 73.7 ± 11.1 |
| EEGNet [15]² | — |
| EEG-Inception [21]¹ | 73.5 ± 9.1 |
| Tensor-SPDNet [32] | 73.0 |
| Multi-view CNN [39] | 72.5 ± 14.1 |
| GNN-SPDNet [33] | 72.0 |
| Hybrid ConvNet [12] | 71.6 |
| Deep ConvNet [12] | 70.9 |
| Residual ConvNet [12] | 67.7 |
| DFNN [52] | — |
| CCNN [38] | — |
| CMO-CNN [10] | — |
| Multi-branch 3D [37] | — |
| TIDNet [19] | — |
| CSP+LDA² | 57.7 ± 14.9 |
| FBCSP+LDA² | 63.7 ± 10.4 |
| TS+LDA² | 65.4 ± 12.9 |
¹ Results reproduced by [22]. ² By us. ³ One subject removed.
3.3 Ouahidi et al. (2024)
Table III. EEG-SimpleConv performance on BNCI on various evaluation setups. Stds (±) on each subject line represent variation across runs, while stds on the Average line represent variation across subjects. (within-subject part.)
| Test | Offline evaluation — W-S, Session 2 | Online evaluation — W-S, Session 2 |
|---|---|---|
| S0 | 86.3 ± 1.3 | 81.0 ± 2.0 |
| S1 | 59.1 ± 1.1 | 54.7 ± 2.4 |
| S2 | 91.3 ± 0.9 | 87.4 ± 1.3 |
| S3 | 77.3 ± 1.7 | 71.9 ± 1.9 |
| S4 | 68.3 ± 2.3 | 44.3 ± 5.0 |
| S5 | 68.3 ± 1.3 | 54.5 ± 4.0 |
| S6 | 89.9 ± 1.0 | 86.5 ± 2.9 |
| S7 | 87.2 ± 1.0 | 84.0 ± 1.7 |
| S8 | 77.8 ± 0.7 | 64.4 ± 1.2 |
| Average | 78.4 ± 10.6 | 70.0 ± 15.1 |
| +EOG | 82.2 ± 9.2 | — |
3.4 Ouahidi et al. (2024)
Table VI. Subject performances using machine-learning baselines on BNCI. Stds (±) represent variation across subjects.
| Subject | TS + LDA | CSP+LDA | FBCSP+LDA |
|---|---|---|---|
| S0 | 77.4 | 68.1 | 75.4 |
| S1 | 52.8 | 52.8 | 56.3 |
| S2 | 84.0 | 73.6 | 78.8 |
| S3 | 60.1 | 53.1 | 64.6 |
| S4 | 47.9 | 27.8 | 50.7 |
| S5 | 49.3 | 42.4 | 47.2 |
| S6 | 64.2 | 55.6 | 74.3 |
| S7 | 74.0 | 71.5 | 63.2 |
| S8 | 78.8 | 74.3 | 63.2 |
| mean | 65.4 ± 12.9 | 57.7 ± 14.9 | 63.7 ± 10.4 |
4 Cross-Session / Within-Subject
| Model | Validation / split | Result (%) | Kappa | Source |
|---|---|---|---|---|
| ATCNet | Original competition holdout | 85.38 | 0.805 | Altaheri et al. (2022) |
| Attention multi-branch CNN | Original competition holdout | 82.87 | 0.772 | Altaheri et al. (2022) |
| Attention multi-scale CNN | Original competition holdout | 79.90 | — | Altaheri et al. (2022) |
| Attention-inception CNN + LSTM | Original competition holdout | 82.84 | — | Altaheri et al. (2022) |
| C2CM | Session T → E | 74.46 | 0.6595 | Song et al. (2022) |
| Conformer | Session T → E | 78.66 | 0.7155 | Song et al. (2022) |
| ConvNet | Session T → E | 72.53 | 0.6337 | Song et al. (2022) |
| DBN-AE | Original competition holdout | 71.00 | — | Altaheri et al. (2022) |
| Deep ConvNet | Holdout (T → E) | 72.22 ± 14.35 | — | Mane et al. (2021) |
| DRDA | Session T → E | 74.74 | 0.6632 | Song et al. (2022) |
| EEG-TCNet | Original competition holdout | 79.55 | 0.73 | Altaheri et al. (2022) |
| EEGNet | Session T → E | 74.50 | 0.6600 | Song et al. (2022) |
| EEGNet-8,2 | Holdout (T → E) | 73.15 ± 9.29 | — | Mane et al. (2021) |
| FBCNet | Holdout (T → E) | 76.20 ± 11.97 | — | Mane et al. (2021) |
| FBCSP | Session T → E | 67.75 | 0.5700 | Song et al. (2022) |
| FBCSP-SVM | Holdout (T → E) | 68.06 ± 14.11 | — | Mane et al. (2021) |
| MAtt | Session 1 → 2 | 74.71 ± 5.01 | — | Pan et al. (2022) |
| Multi-layer-CNN + MLP | Original competition holdout | 75.00 | — | Altaheri et al. (2022) |
| Shallow CNN | Original competition holdout | 74.31 | 0.66 | Altaheri et al. (2022) |
| TCNet_Fusion | Original competition holdout | 80.67 | 0.74 | Altaheri et al. (2022) |
4.1 Song et al. (2022)
Comparisons with state-of-the-art methods on Datasets I.
| Dataset | Method | S01 | S02 | S03 | S04 | S05 | S06 | S07 | S08 | S09 | Average | Kappa |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| I | FBCSP [8] | 76.00 | 56.50 | 81.25 | 61.00 | 55.00 | 45.25 | 82.75 | 81.25 | 70.75 | 67.75 | 0.5700 |
| I | ConvNet [16] | 76.39 | 55.21 | 89.24 | 74.65 | 56.94 | 54.17 | 92.71 | 77.08 | 76.39 | 72.53 | 0.6337 |
| I | EEGNet [17] | 85.76 | 61.46 | 88.54 | 67.01 | 55.90 | 52.08 | 89.58 | 83.33 | 86.81 | 74.50 | 0.6600 |
| I | C2CM [28] | 87.50 | 65.28 | 90.28 | 66.67 | 62.50 | 45.49 | 89.58 | 83.33 | 79.51 | 74.46 | 0.6595 |
| I | FBCNet [38] | 85.42 | 60.42 | 90.63 | 76.39 | 74.31 | 53.82 | 84.38 | 79.51 | 80.90 | 76.20 | 0.6827 |
| I | DRDA [39] | 83.19 | 55.14 | 87.43 | 75.28 | 62.29 | 57.15 | 86.18 | 83.61 | 82.00 | 74.74 | 0.6632 |
| I | Conformer | 88.19 | 61.46 | 93.40 | 78.13 | 52.08 | 65.28 | 92.36 | 88.19 | 88.89 | 78.66 | 0.7155 |
4.2 Zhong et al. (2024)
Table II. Inter-session classification performance comparisons of different methods on BCI Competition IV Dataset 2A (in percent %).
| Method | A01 | A02 | A03 | A04 | A05 | A06 | A07 | A08 | A09 | Mean±Std | Kappa (×100) | Rank |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FBCSP [9] | 76.00 | 56.50 | 81.25 | 61.00 | 55.00 | 45.25 | 82.75 | 81.25 | 70.75 | 67.75±13.73 | 57.00 | 9.6 |
| CCSP [8] | 84.72 | 52.78 | 80.90 | 59.38 | 54.51 | 49.31 | 88.54 | 71.88 | 56.60 | 66.51±15.13 | 55.35 | 9.4 |
| ConvNet [11] | 76.39 | 55.21 | 89.24 | 74.65 | 56.94 | 54.17 | 92.71 | 77.08 | 76.39 | 72.53±14.24 | 63.38 | 7.4 |
| EEGNet [12] | 79.86 | 58.68 | 89.93 | 64.93 | 63.19 | 58.68 | 64.24 | 73.61 | 77.08 | 70.22±10.72 | 66.33 | 7.7 |
| C2CM [13] | 87.50 | 65.28 | 90.28 | 66.67 | 62.50 | 45.49 | 89.58 | 83.33 | 79.51 | 74.46±15.33 | 65.96 | 5.3 |
| DRDA [35] | 83.19 | 55.14 | 87.43 | 75.28 | 62.29 | 57.15 | 86.18 | 83.61 | 82.00 | 74.75±12.96 | 66.33 | 6.8 |
| DJDAN [17] | 85.77 | 63.25 | 93.41 | 76.75 | 62.68 | 69.77 | 87.37 | 86.72 | 85.61 | 79.03±11.35 | 72.04 | 3.7 |
| DAFS [34] | 81.94 | 64.58 | 88.89 | 73.61 | 70.49 | 56.60 | 85.42 | 79.51 | 81.60 | 75.85±10.47 | 67.80 | 6.1 |
| DAWD [19] | 83.29 | 63.97 | 90.30 | 76.94 | 69.34 | 60.08 | 89.31 | 82.35 | 82.81 | 77.60±10.85 | 69.51 | 4.0 |
| GAT [36] | 88.89 | 61.11 | 93.40 | 71.86 | 50.35 | 60.07 | 89.58 | 87.50 | 86.46 | 76.58±15.98 | 68.77 | 4.4 |
| Our Method | 89.24 | 64.93 | 94.79 | 85.76 | 68.75 | 61.46 | 95.14 | 88.89 | 87.15 | 81.79±13.06 | 75.72 | 1.4 |
4.3 Altaheri et al. (2022)
Table 5. Subject-specific performance on the BCI-2a dataset using the same original competition division (hold-out approach: 50% training trials and 50% test trials). Accuracy (%) and κ-score are the averages for all subjects.
| Method | Accuracy | κ-score |
|---|---|---|
| Shallow CNN [32] | 74.31 | 0.66 |
| EEGNet: CNN [12]* | 80.59 | 0.74 |
| DBN-AE [17] | 71.0 | — |
| Multi-layer-CNN and MLP [18] | 75.0 | — |
| EEG-TCNet: CNN and TCN [22]* | 79.55 | 0.73 |
| Attention multi-scale CNN [13] | 79.9 | — |
| TCNet_Fusion: multi-layer CNN + TCN [23]* | 80.67 | 0.74 |
| Attention-inception CNN & LSTM [10] | 82.84 | — |
| Attention multi-branch CNN [9] | 82.87 | 0.772 |
| ATCNet: Attention-CNN and TCN (Proposed) | 85.38 | 0.805 |
| * Reproduced. |
4.4 Ingolfsson et al. (2020)
Table III. Classification accuracy (%) and κ scores on the 4-class MI BCI Competition IV-2a dataset.
| Subj. | Fixed Networks — EEGNet [10] Accuracy | Fixed Networks — EEGNet [10] κ | Fixed Networks — Shallow ConvNet [9] Accuracy | Fixed Networks — Shallow ConvNet [9] κ | Fixed Networks — EEG-TCNet Accuracy | Fixed Networks — EEG-TCNet κ | Variable Networks — EEGNet Accuracy | Variable Networks — EEGNet κ | Variable Networks — EEG-TCNet Accuracy | Variable Networks — EEG-TCNet κ | Variable Networks — DFFN [11] Accuracy |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | 84.34 | 0.79 | 79.51 | 0.73 | 85.77 | 0.81 | 86.48 | 0.82 | 89.32 | 0.86 | 83.46 |
| 2 | 54.06 | 0.39 | 56.25 | 0.42 | 65.02 | 0.53 | 61.84 | 0.49 | 72.44 | 0.63 | 69.30 |
| 3 | 87.54 | 0.83 | 88.89 | 0.85 | 94.51 | 0.93 | 93.41 | 0.91 | 97.44 | 0.97 | 90.29 |
| 4 | 63.59 | 0.51 | 80.90 | 0.75 | 64.91 | 0.53 | 73.25 | 0.64 | 75.87 | 0.68 | 71.07 |
| 5 | 67.39 | 0.57 | 57.29 | 0.43 | 75.36 | 0.67 | 76.81 | 0.69 | 83.69 | 0.78 | 65.41 |
| 6 | 54.88 | 0.39 | 53.82 | 0.38 | 61.40 | 0.49 | 59.07 | 0.45 | 70.69 | 0.61 | 69.45 |
| 7 | 88.80 | 0.85 | 91.67 | 0.89 | 87.36 | 0.83 | 90.25 | 0.87 | 93.14 | 0.91 | 88.18 |
| 8 | 76.75 | 0.69 | 81.25 | 0.75 | 83.76 | 0.78 | 87.45 | 0.83 | 86.71 | 0.82 | 86.76 |
| 9 | 74.24 | 0.65 | 79.17 | 0.72 | 78.03 | 0.71 | 82.95 | 0.77 | 85.23 | 0.80 | 93.54 |
| Mean | 72.40 | 0.63 | 74.31 | 0.66 | 77.35 | 0.70 | 79.06 | 0.72 | 83.84 | 0.78 | 79.71 |
| Std. Dev. | 13.27 | 0.18 | 14.54 | 0.19 | 11.57 | 0.15 | 12.28 | 0.16 | 9.20 | 0.12 | 10.79 |
| * Reproduced. |
4.5 Mane et al. (2021) Hold Out (T → E)
Table S3. Classification accuracies for each subject in BCIC-IV-2A Dataset. (hold-out part.)
| Subj. | Hold Out — FBCSP-SVM | Hold Out — Deep Convnet | Hold Out — EEGNet-8,2 | Hold Out — FBCNet |
|---|---|---|---|---|
| 1 | 77.78 | 78.13 | 79.51 | 85.42 |
| 2 | 55.56 | 45.14 | 61.11 | 60.42 |
| 3 | 79.51 | 85.42 | 88.54 | 90.63 |
| 4 | 63.19 | 67.01 | 71.53 | 76.39 |
| 5 | 53.47 | 77.43 | 71.18 | 74.31 |
| 6 | 46.88 | 53.13 | 59.03 | 53.82 |
| 7 | 86.81 | 86.46 | 71.53 | 84.38 |
| 8 | 81.25 | 78.13 | 80.56 | 79.51 |
| 9 | 68.06 | 79.17 | 75.35 | 80.90 |
| Avg | 68.06 | 72.22 | 73.15 | 76.20 |
| Std | 14.11 | 14.35 | 9.29 | 11.97 |
4.6 Riyad et al. (2021)
Table 1. Classification accuracy (%) comparison of our methods and the baselines; Sd stands for standard deviation.
| Subj. | Baselines — FBCSP | Baselines — RG | Baselines — ShallowConvNet | AMSI-EEGNet — CTC | AMSI-EEGNet — CSTC | AMSI-EEGNet — Original |
|---|---|---|---|---|---|---|
| S1 | 75.69 | 77.78 | 89.58 | 83.33 | 78.12 | 84.03 |
| S2 | 44.79 | 43.75 | 51.04 | 48.26 | 47.57 | 55.21 |
| S3 | 85.07 | 83.68 | 92.01 | 89.24 | 88.54 | 89.58 |
| S4 | 63.54 | 56.60 | 69.79 | 68.40 | 58.33 | 69.79 |
| S5 | 59.03 | 47.92 | 44.44 | 63.54 | 57.99 | 66.32 |
| S6 | 36.46 | 47.57 | 58.68 | 56.94 | 52.08 | 61.46 |
| S7 | 86.11 | 78.47 | 94.79 | 91.32 | 91.32 | 94.10 |
| S8 | 79.17 | 79.86 | 83.68 | 86.11 | 80.21 | 85.07 |
| S9 | 82.64 | 81.25 | 79.51 | 80.21 | 81.94 | 80.90 |
| Average | 68.06 | 66.32 | 73.72 | 74.15 | 70.68 | 76.27 |
| Sd | 17.16 | 15.92 | 17.56 | 14.52 | 15.68 | 12.73 |
4.7 Ju et al. (2022)
Table II. Average accuracies and standard deviations for the subject-specific analysis of MI-KU (54 subjects) and BCIC-IV-2a (9 subjects). Each result is average accuracy (standard deviation); the best-performing number for each analysis is bold. (cross-session part.)
| Method | MI-KU — Holdout (S1 → S2) % | BCIC-IV-2a — Holdout (T → E) % |
|---|---|---|
| FBCSP | 59.67 (14.32) | 65.79 (14.21) |
| MDM | 52.33 (6.74) | 50.74 (13.80) |
| TSM | 51.65 (6.11) | 49.72 (12.39) |
| SPDNet | 60.41 (12.13) | 55.67 (9.54) |
| EEGNet | 63.28 (11.56) | 60.31 (10.52) |
| ConvNet | 61.47 (11.22) | 57.61 (11.09) |
| FBCNet | 67.83 (14.34) | 72.71 (14.67) |
| Tensor-CSPNet | 69.65 (14.97) | 72.96 (14.98) |
4.8 Kobler et al. (2022)
| Dataset | UDA | Method | Inter-session (degrees of freedom / # classes: 17 / 4) |
|---|---|---|---|
| BNCI2014001 | no | FBCSP+SVM | • 60.6 (4.9) |
| BNCI2014001 | no | TSM+SVM | • 61.8 (4.1) |
| BNCI2014001 | no | FB+TSM+LR | 69.8 (4.8) |
| BNCI2014001 | no | EEGNet | • 41.8 (5.8) |
| BNCI2014001 | no | ShConvNet | • 51.3 (2.3) |
| BNCI2014001 | yes | FBCSP+DSS+LDA | 71.3 (1.8) |
| BNCI2014001 | yes | URPA+MDM | • 59.5 (2.7) |
| BNCI2014001 | yes | SPDOT+TSM+SVM | 66.8 (3.8) |
| BNCI2014001 | yes | EEGNet+DANN | • 50.0 (7.7) |
| BNCI2014001 | yes | ShConvNet+DANN | • 51.6 (3.2) |
| BNCI2014001 | yes | TSMNet(SPDDSMBN) | 69.0 (3.6) |
4.9 Peng et al. (2023)
Two-class (left vs right hand) original train/test split. The Mean ± Std pools all 12 subjects across IIIa (B1–B3) and 2a (C1–C9) — the paper does not report per-dataset means, so these are not 2a-specific values.
| Method | Accuracy — Mean ± Std | BCI Competition III Dataset IIIa — B1 | BCI Competition III Dataset IIIa — B2 | BCI Competition III Dataset IIIa — B3 | BCI Competition IV Dataset IIa — C1 | BCI Competition IV Dataset IIa — C2 | BCI Competition IV Dataset IIa — C3 | BCI Competition IV Dataset IIa — C4 | BCI Competition IV Dataset IIa — C5 | BCI Competition IV Dataset IIa — C6 | BCI Competition IV Dataset IIa — C7 | BCI Competition IV Dataset IIa — C8 | BCI Competition IV Dataset IIa — C9 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MDRM [8] | 78.5 ± 16.1 | 97.8 | 63.3 | 88.3 | 88.2 | 52.8 | 92.4 | 71.5 | 58.3 | 64.6 | 75 | 95.8 | 94.4 |
| CSP+LDA [2] | 79.4 ± 16.8 | 95.6 | 61.7 | 93.3 | 88.9 | 51.4 | 96.5 | 70.1 | 54.9 | 71.5 | 81.3 | 93.8 | 93.8 |
| Ga-DR [17] | 78.2 ± 14.9 | 96.7 | 68.3 | 85 | 87.5 | 53.5 | 92.4 | 73.6 | 57.6 | 68.0 | 70.8 | 94.4 | 91.6 |
| Ga-PCA [18] | 68.5 ± 13.0 | 80 | 63.3 | 68.3 | 77.8 | 50 | 84.7 | 64.5 | 53.4 | 56.9 | 56.2 | 84.0 | 84.0 |
| DPLM [19] | 75.6 ± 15.3 | 85.6 | 63.3 | 75 | 89.6 | 56.9 | 93.1 | 70.8 | 56.9 | 58.3 | 68.0 | 95.1 | 94.4 |
| SPD-Net [26] | 76.9 ± 17.1 | 97.7 | 66.7 | 88.3 | 84.7 | 56.3 | 93.8 | 68.1 | 56.9 | 62.5 | 56.3 | 95.8 | 95.1 |
| SPD-Mani-Net | 83.1 ± 14.9 | 100 | 66.7 | 98.3 | 94.4 | 57.6 | 93.1 | 75 | 71.5 | 66.7 | 83.3 | 96.5 | 94.4 |
5 Cross-Subject
5.1 Chen et al. (2024)
Cross-subject STS (source-to-target) classification accuracies (%) on BNCI2014001. Subjects A1–A5 are selected for STS cross-subject MI classification tasks, giving A₂⁵ = 20 STS tasks in total. (An earlier version of this note had this section misattributed — the offline/online transfer-learning table previously here belongs to Li et al. (2024) and is audited in §5.4.)
| Dataset | STS Task | DeepConvNet | EEGNet | DDC | DDAN | DDAF-C | DAWD | BDAN |
|---|---|---|---|---|---|---|---|---|
| BCIC-IV-2a (4 Classes) | A1 → A2 | 47.86% | 41.07% | 45.71% | 48.21% | 47.86% | 47.50% | 53.21% |
| BCIC-IV-2a (4 Classes) | A1 → A3 | 59.64% | 56.43% | 59.29% | 58.93% | 61.79% | 59.29% | 67.86% |
| BCIC-IV-2a (4 Classes) | A1 → A4 | 51.43% | 48.21% | 51.07% | 52.86% | 52.86% | 53.93% | 60.36% |
| BCIC-IV-2a (4 Classes) | A1 → A5 | 45.00% | 40.36% | 49.29% | 46.07% | 45.71% | 45.36% | 52.50% |
| BCIC-IV-2a (4 Classes) | A2 → A1 | 50.00% | 45.36% | 47.14% | 50.00% | 50.00% | 48.57% | 56.79% |
| BCIC-IV-2a (4 Classes) | A2 → A3 | 46.79% | 47.14% | 48.57% | 48.57% | 51.07% | 46.07% | 57.14% |
| BCIC-IV-2a (4 Classes) | A2 → A4 | 48.21% | 42.50% | 51.43% | 54.64% | 53.93% | 50.00% | 55.71% |
| BCIC-IV-2a (4 Classes) | A2 → A5 | 49.64% | 54.29% | 60.71% | 55.36% | 52.86% | 59.29% | 64.64% |
| BCIC-IV-2a (4 Classes) | A3 → A1 | 61.43% | 54.64% | 61.07% | 66.43% | 65.36% | 61.79% | 71.43% |
| BCIC-IV-2a (4 Classes) | A3 → A2 | 46.43% | 44.64% | 46.43% | 50.00% | 48.21% | 45.00% | 53.21% |
| BCIC-IV-2a (4 Classes) | A3 → A4 | 51.79% | 48.21% | 52.86% | 53.93% | 50.00% | 53.93% | 55.00% |
| BCIC-IV-2a (4 Classes) | A3 → A5 | 46.79% | 41.43% | 45.36% | 50.71% | 49.29% | 47.50% | 52.50% |
| BCIC-IV-2a (4 Classes) | A4 → A1 | 54.64% | 50.36% | 53.21% | 54.29% | 53.93% | 53.93% | 63.21% |
| BCIC-IV-2a (4 Classes) | A4 → A2 | 48.21% | 47.14% | 50.00% | 50.36% | 50.00% | 49.64% | 55.36% |
| BCIC-IV-2a (4 Classes) | A4 → A3 | 54.64% | 51.79% | 54.29% | 56.07% | 56.43% | 52.86% | 57.86% |
| BCIC-IV-2a (4 Classes) | A4 → A5 | 47.14% | 42.14% | 49.64% | 51.43% | 52.14% | 50.71% | 59.29% |
| BCIC-IV-2a (4 Classes) | A5 → A1 | 45.71% | 47.86% | 48.57% | 49.64% | 48.21% | 50.00% | 58.93% |
| BCIC-IV-2a (4 Classes) | A5 → A2 | 51.79% | 54.64% | 58.21% | 54.64% | 56.43% | 56.07% | 66.79% |
| BCIC-IV-2a (4 Classes) | A5 → A3 | 46.43% | 43.21% | 46.43% | 48.21% | 48.93% | 44.29% | 55.36% |
| BCIC-IV-2a (4 Classes) | A5 → A4 | 47.14% | 52.14% | 51.07% | 51.07% | 55.36% | 48.93% | 58.57% |
| BCIC-IV-2a (4 Classes) | Average | 50.04% | 47.68% | 51.52% | 52.57% | 52.52% | 51.23% | 58.79% |
5.2 Wei et al. (2024)
BDAN-SPD evaluates cross-subject transfer on BCIC-IV-2a/2b and OpenBMI with leave-one-subject-out and labeled target calibration (not calibration-free). BCIC-IV-2a (9 tasks): accuracy 77.49 ± 15.22; kappa 0.6998 per Table III, while the paper text states 0.6905 (text/table discrepancy). The full comparison table (FBCSP, EA-CSP-LDA, ssCSP, SSMM, RA-MDRM, ShallowConvNet, EEGNet, SHNN, MI-CNN, MIN2Net, DRDA, GAT baselines) is audited in BCI Competition IV Dataset 2b. (An earlier version of this note attributed Chen et al.’s pairwise STS table to Wei et al. — corrected in this audit.)
5.3 Peng et al. (2023)
Four-class “multi-subject” experiment: all subjects’ signals are merged into one training/testing set (merged-subject, not held-out-subject cross-subject). The Mean ± Std pools all 12 subjects across IIIa (B1–B3) and 2a (C1–C9) — not 2a-specific.
| Method | Accuracy — Mean ± Std | BCI Competition III Dataset IIIa — B1 | BCI Competition III Dataset IIIa — B2 | BCI Competition III Dataset IIIa — B3 | BCI Competition IV Dataset IIa — C1 | BCI Competition IV Dataset IIa — C2 | BCI Competition IV Dataset IIa — C3 | BCI Competition IV Dataset IIa — C4 | BCI Competition IV Dataset IIa — C5 | BCI Competition IV Dataset IIa — C6 | BCI Competition IV Dataset IIa — C7 | BCI Competition IV Dataset IIa — C8 | BCI Competition IV Dataset IIa — C9 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MDRM [8] | 43.61 ± 16.71 | 67.78 | 39.17 | 27.50 | 61.46 | 27.08 | 64.93 | 39.93 | 25.00 | 22.22 | 61.46 | 46.88 | 39.93 |
| SPD-Net [26] | 45.75 ± 17.56 | 70.56 | 36.67 | 38.33 | 66.67 | 26.74 | 69.80 | 37.50 | 25.35 | 26.04 | 55.21 | 60.07 | 36.11 |
| SPD-Mani-Net | 48.21 ± 15.73 | 65.00 | 33.33 | 35.00 | 65.28 | 28.13 | 68.75 | 45.49 | 29.51 | 34.03 | 51.74 | 64.58 | 57.64 |
| SPD-Mani-Net+Reg | 53.28 ± 17.78 | 83.30 | 43.30 | 32.50 | 61.11 | 33.33 | 69.44 | 42.71 | 39.24 | 32.99 | 62.85 | 69.44 | 69.10 |
5.4 Li et al. (2024)
*Table II. Cross-subject classification accuracies (%) on BNCI2014001. The best accuracies in offline TL are marked with . The best accuracies in online TL are marked in bold, and the second best by an underline.
| Setting | Approach | S0 | S1 | S2 | S3 | S4 | S5 | S6 | S7 | S8 | Avg. |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Baselines | CSP (w/o EA) | 82.64 | 50.69 | 69.44 | 66.67 | 47.22 | 62.50 | 71.53 | 88.19 | 68.06 | 67.44 |
| Baselines | EEGNet (w/o EA) | 73.61 | 55.69 | 81.67 | 64.44 | 51.25 | 75.00 | 58.19 | 90.28 | 81.53 | 70.19±1.87 |
| Offline TL | CSP | 83.33 | 52.08 | 97.92 | 75.00* | 56.25 | 67.36 | 72.22* | 88.19 | 71.53 | 73.77 |
| Offline TL | EEGNet | 83.19 | 60.28 | 92.08 | 67.92 | 57.22 | 72.50 | 64.86 | 86.11 | 79.44 | 73.73±1.11 |
| Offline TL | DAN | 76.67 | 63.89* | 94.44 | 70.42 | 59.31 | 75.69 | 63.75 | 84.72 | 80.83 | 74.41±1.05 |
| Offline TL | JAN | 81.94 | 63.89* | 90.97 | 71.94 | 60.56 | 72.64 | 68.33 | 83.89 | 83.06 | 75.25±1.34 |
| Offline TL | DANN | 82.64 | 60.97 | 91.39 | 68.89 | 63.47* | 79.31* | 65.42 | 84.31 | 82.36 | 75.42±0.79 |
| Offline TL | CDAN-E | 80.14 | 63.33 | 92.36 | 71.11 | 57.92 | 74.03 | 68.33 | 87.78 | 87.36 | 75.82±0.66 |
| Offline TL | MDD | 79.31 | 57.64 | 94.44 | 70.42 | 57.92 | 73.33 | 65.97 | 84.03 | 86.25 | 74.37±1.50 |
| Offline TL | MCC | 86.81* | 62.36 | 98.47* | 73.19 | 58.61 | 72.64 | 66.94 | 94.17* | 96.39* | 78.84±0.82 |
| Offline TL | SHOT | 81.39 | 61.25 | 93.47 | 64.31 | 60.97 | 75.28 | 65.56 | 85.14 | 86.94 | 74.92±0.74 |
| Offline TL | SHOT-IM | 84.44 | 63.33 | 94.31 | 70.83 | 61.67 | 75.28 | 70.42 | 87.64 | 86.81 | 77.19±1.41 |
| Online TL | CSP | 80.56 | 53.47 | 96.53 | 72.22 | 54.86 | 63.89 | 72.92 | 88.19 | 72.22 | 72.76 |
| Online TL | EEGNet | 82.22 | 60.56 | 92.50 | 67.78 | 56.39 | 72.64 | 64.17 | 85.28 | 80.14 | 73.52±1.14 |
| Online TL | BN-adapt | 80.83 | 59.72 | 92.78 | 69.44 | 57.64 | 72.08 | 67.08 | 84.86 | 86.39 | 74.54±1.70 |
| Online TL | Tent | 78.89 | 58.75 | 92.92 | 69.03 | 57.22 | 72.36 | 67.78 | 85.28 | 86.67 | 74.32±1.43 |
| Online TL | PL | 78.75 | 57.64 | 94.44 | 66.53 | 59.44 | 72.36 | 69.86 | 88.61 | 88.33 | 75.11±0.89 |
| Online TL | T3A | 82.50 | 51.53 | 93.19 | 55.28 | 49.72 | 58.06 | 57.78 | 84.17 | 81.81 | 68.23±1.19 |
| Online TL | CoTTA | 75.69 | 59.31 | 91.94 | 66.81 | 55.56 | 71.67 | 62.78 | 84.44 | 80.14 | 72.04±0.56 |
| Online TL | SAR | 83.47 | 57.50 | 95.28 | 67.08 | 54.72 | 71.53 | 63.19 | 89.72 | 90.69 | 74.80±0.48 |
| Online TL | T-TIME | 84.03 | 60.56 | 95.69 | 67.64 | 57.22 | 73.33 | 67.22 | 91.25 | 90.97 | 76.44±0.55 |
| Online TL | T-TIME (5) | 84.93 | 63.54 | 96.88 | 70.83 | 62.78 | 77.22 | 71.81 | 92.22 | 93.47 | 79.30±0.82 |
5.5 Altaheri et al. (2022)
Table 6. Subject-independent performance on the BCI-2a dataset using leave-one-subject-out (LOSO) cross-validation. Accuracy (%) and κ-score are the averages for all subjects.
| Method | Accuracy | κ-score |
|---|---|---|
| Attention graph convolutional network [8] | 60.1 | - |
| Multi-layer-CNN and AE [18] | 55.3 | - |
| EEGNet: CNN [12]* | 68.79 | 0.584 |
| Attention multi-branch CNN [9] | 69.10 | - |
| EEG-TCNet: CNN and TCN [22]* | 69.52 | 0.594 |
| TCNet_Fusion: multi-layer CNN + TCN [23]* | 70.58 | 0.608 |
| ATCNet: Attention-CNN and TCN (Proposed) | 70.97 | 0.613 |
| * Reproduced. |
5.6 Song et al. (2021)
Table IV. Classification accuracy (in percentage %) under different augmentation situations.
| Augmentation situation | S01 | S02 | S03 | S04 | S05 | S06 | S07 | S08 | S09 | Accuracy |
|---|---|---|---|---|---|---|---|---|---|---|
| Leave-one-subject-out | 69.10 | 36.81 | 60.76 | 45.83 | 33.33 | 42.71 | 45.83 | 65.97 | 68.75 | 52.12±14.08 |
| adapt 100 real samples | 72.87 | 42.55 | 70.74 | 53.72 | 40.96 | 41.49 | 66.49 | 76.06 | 69.68 | 59.40±14.67 |
| adapt 100 fake samples | 77.13 | 38.30 | 69.15 | 51.60 | 39.36 | 39.89 | 65.96 | 78.72 | 62.77 | 58.10±16.24 |
| adapt 3000 fake samples | 81.91 | 53.19 | 79.26 | 60.11 | 44.68 | 49.47 | 80.32 | 84.04 | 78.72 | 67.97±15.86 |
5.7 Rodrigues et al. (2019) - RPA (Cross-Subject Transfer Learning)
| Dataset | N | Mean AUC — DCT | Mean AUC — RCT | Mean AUC — PRL | Mean AUC — OPT | Mean AUC — RPA |
|---|---|---|---|---|---|---|
| BNCI2014001 | 1 | 0.58 | 0.69 | 0.69 | 0.65 | 0.62 |
| BNCI2014001 | 6 | 0.59 | 0.73 | 0.73 | 0.65 | 0.71 |
| BNCI2014001 | 18 | 0.61 | 0.76 | 0.76 | 0.65 | 0.76 |
| BNCI2014001 | 36 | 0.64 | 0.78 | 0.77 | 0.66 | 0.79 |
5.8 Kobler et al. (2022) - Inter-Subject
| Dataset | UDA | Method | Inter-subject (degrees of freedom / # classes: 8 / 4) |
|---|---|---|---|
| BNCI2014001 | no | FBCSP+SVM | • 32.3 (7.3) |
| BNCI2014001 | no | TSM+SVM | • 34.7 (8.6) |
| BNCI2014001 | no | FB+TSM+LR | • 36.5 (8.2) |
| BNCI2014001 | no | EEGNet | • 43.3 (17.0) |
| BNCI2014001 | no | ShConvNet | • 42.2 (16.2) |
| BNCI2014001 | yes | FBCSP+DSS+LDA | 48.3 (14.3) |
| BNCI2014001 | yes | URPA+MDM | 46.8 (14.6) |
| BNCI2014001 | yes | SPDOT+TSM+SVM | • 38.6 (8.6) |
| BNCI2014001 | yes | EEGNet+DANN | 45.8 (18.0) |
| BNCI2014001 | yes | ShConvNet+DANN | • 42.2 (13.6) |
| BNCI2014001 | yes | TSMNet(SPDDSMBN) | 51.6 (16.5) |
5.9 Ouahidi et al. (2024)
Table II. Performance comparison to literature methods on BNCI using offline evaluation setups. Standard deviations (stds or ±) represent variation across subjects. (cross-subject part.)
EEG-SimpleConv through TIDNet are deep-learning methods; CSP+LDA, FBCSP+LDA, and TS+LDA are machine-learning methods.
| Method | Cross-Subject (C-S) | C-S F-T |
|---|---|---|
| EEG-SimpleConv | 72.1 ± 7.3 | 86.2 ± 6.3 |
| EEG Conformer [30] | — | — |
| EEG-ITNet [22] | 69.4 ± 8.9 | 78.7 ± 9.4 |
| EEG-TCNet [18]¹ | 65.1 ± 10.9 | 75.8 ± 10.2 |
| CNN-SPDNet [35] | — | — |
| Shallow ConvNet [12] | — | — |
| EEGNet [15]¹ | 64.0 ± 11.6 | 73.9 ± 12.2 |
| EEGNet [15]² | 66.2 ± 9.9 | — |
| EEG-Inception [21]¹ | 66.3 ± 8.7 | 75.0 ± 9.8 |
| Tensor-SPDNet [32] | — | — |
| Multi-view CNN [39] | — | — |
| GNN-SPDNet [33] | — | — |
| Hybrid ConvNet [12] | — | — |
| Deep ConvNet [12] | — | — |
| Residual ConvNet [12] | — | — |
| DFNN [52] | 64.4 | — |
| CCNN [38] | 55.3 | — |
| CMO-CNN [10] | 63.3 | — |
| Multi-branch 3D [37] | 52.2 | — |
| TIDNet [19] | 65.4³ | 77.4³ |
| CSP+LDA² | — | — |
| FBCSP+LDA² | — | — |
| TS+LDA² | — | — |
| ¹ Results reproduced by [22]. ² By us. ³ One subject removed. |
5.10 Ouahidi et al. (2024)
Table III. EEG-SimpleConv performance on BNCI on various evaluation setups. Stds (±) on each subject line represent variation across runs, while stds on the Average line represent variation across subjects. (cross-subject part.)
| Test | Offline evaluation — C-S, Sessions 1&2 | Offline evaluation — C-S, Session 2 | Offline evaluation — C-S F-T, Session 2 | Online evaluation — C-S, Sessions 1&2 | Online evaluation — C-S, Session 2 | Online evaluation — C-S F-T, Session 2 |
|---|---|---|---|---|---|---|
| S0 | 78.9 ± 1.7 | 79.7 ± 1.5 | 89.0 ± 1.5 | 62.5 ± 1.5 | 64.7 ± 2.0 | 86.0 ± 1.1 |
| S1 | 57.7 ± 1.4 | 57.3 ± 1.9 | 72.8 ± 2.3 | 50.2 ± 1.0 | 49.0 ± 2.0 | 65.8 ± 4.0 |
| S2 | 83.0 ± 1.1 | 85.4 ± 2.4 | 94.1 ± 1.3 | 67.4 ± 2.3 | 66.8 ± 3.2 | 87.6 ± 1.6 |
| S3 | 66.7 ± 1.6 | 71.5 ± 2.2 | 89.3 ± 0.8 | 54.5 ± 3.0 | 57.6 ± 3.2 | 85.7 ± 1.8 |
| S4 | 70.9 ± 1.8 | 71.0 ± 2.0 | 82.2 ± 2.0 | 56.0 ± 2.7 | 54.9 ± 4.1 | 71.5 ± 3.0 |
| S5 | 66.6 ± 0.7 | 65.6 ± 1.5 | 80.3 ± 2.3 | 47.2 ± 2.7 | 44.8 ± 2.4 | 68.8 ± 4.5 |
| S6 | 75.7 ± 1.3 | 74.0 ± 1.9 | 92.9 ± 0.6 | 69.1 ± 1.5 | 70.2 ± 2.0 | 74.8 ± 1.7 |
| S7 | 77.5 ± 1.5 | 78.1 ± 1.0 | 88.7 ± 1.4 | 60.9 ± 2.6 | 62.2 ± 2.2 | 86.7 ± 1.5 |
| S8 | 71.6 ± 1.6 | 71.7 ± 1.9 | 86.1 ± 1.2 | 58.0 ± 3.8 | 54.3 ± 4.1 | 81.9 ± 2.8 |
| Average | 72.1 ± 7.3 | 72.7 ± 7.7 | 86.2 ± 6.3 | 58.4 ± 6.9 | 58.3 ± 7.9 | 78.8 ± 8.1 |
| +EOG | 79.6 ± 6.1 | 80.1 ± 7.2 | 90.2 ± 5.5 | — | — | — |